 Protect your privacy and browse without limits, with our official lightning-fast VPN app.Get Your Private VPN →Protect your privacy and browse without limits, with our official lightning-fast VPN app.Get Your Private VPN →
November 03, 2026
Learn how to scrape websites without blocks using adaptive rate limits, reliable proxies, sticky sessions, retries, monitoring, and practical fixes safely.
Scraping without getting blocked is not about sending more requests or changing IPs after every failure. Reliable collection comes from controlling request rate, choosing the right proxy type, preserving session identity, and reacting to server signals. This guide explains how to build those controls into a production scraper so it gathers permitted public data consistently while reducing 403 responses, 429 rate limits, CAPTCHA challenges, and wasted proxy traffic.
Websites use several layers of protection. Basic systems count requests per IP, while more advanced defenses correlate cookies, headers, TLS characteristics, navigation patterns, and browser behavior. A scraper can therefore be blocked even when every request uses a different address.
Before collecting data, review the website's terms, robots directives, applicable law, and access restrictions. Prefer an official API when it provides the required data. Do not bypass authentication, access private information, or evade controls that protect restricted content.
A safe initial rate is deliberately conservative. Start with one worker per domain and one request every two to five seconds. Add random variation so the interval is not mechanically fixed. Measure the result for each target because a small website and a global marketplace will not tolerate the same load.
Set limits at three levels: per domain, per proxy, and per session. A global queue alone is insufficient because several workers may still overload the same host or exit IP. Token bucket and leaky bucket algorithms are useful because they support a steady baseline while allowing a small, controlled burst.
A practical retry schedule might wait 2, 5, 15, and 45 seconds, with 20 to 40 percent random jitter. Cap retries at three or four attempts and move persistent failures to a delayed queue. Unlimited retries increase costs and make blocks last longer.
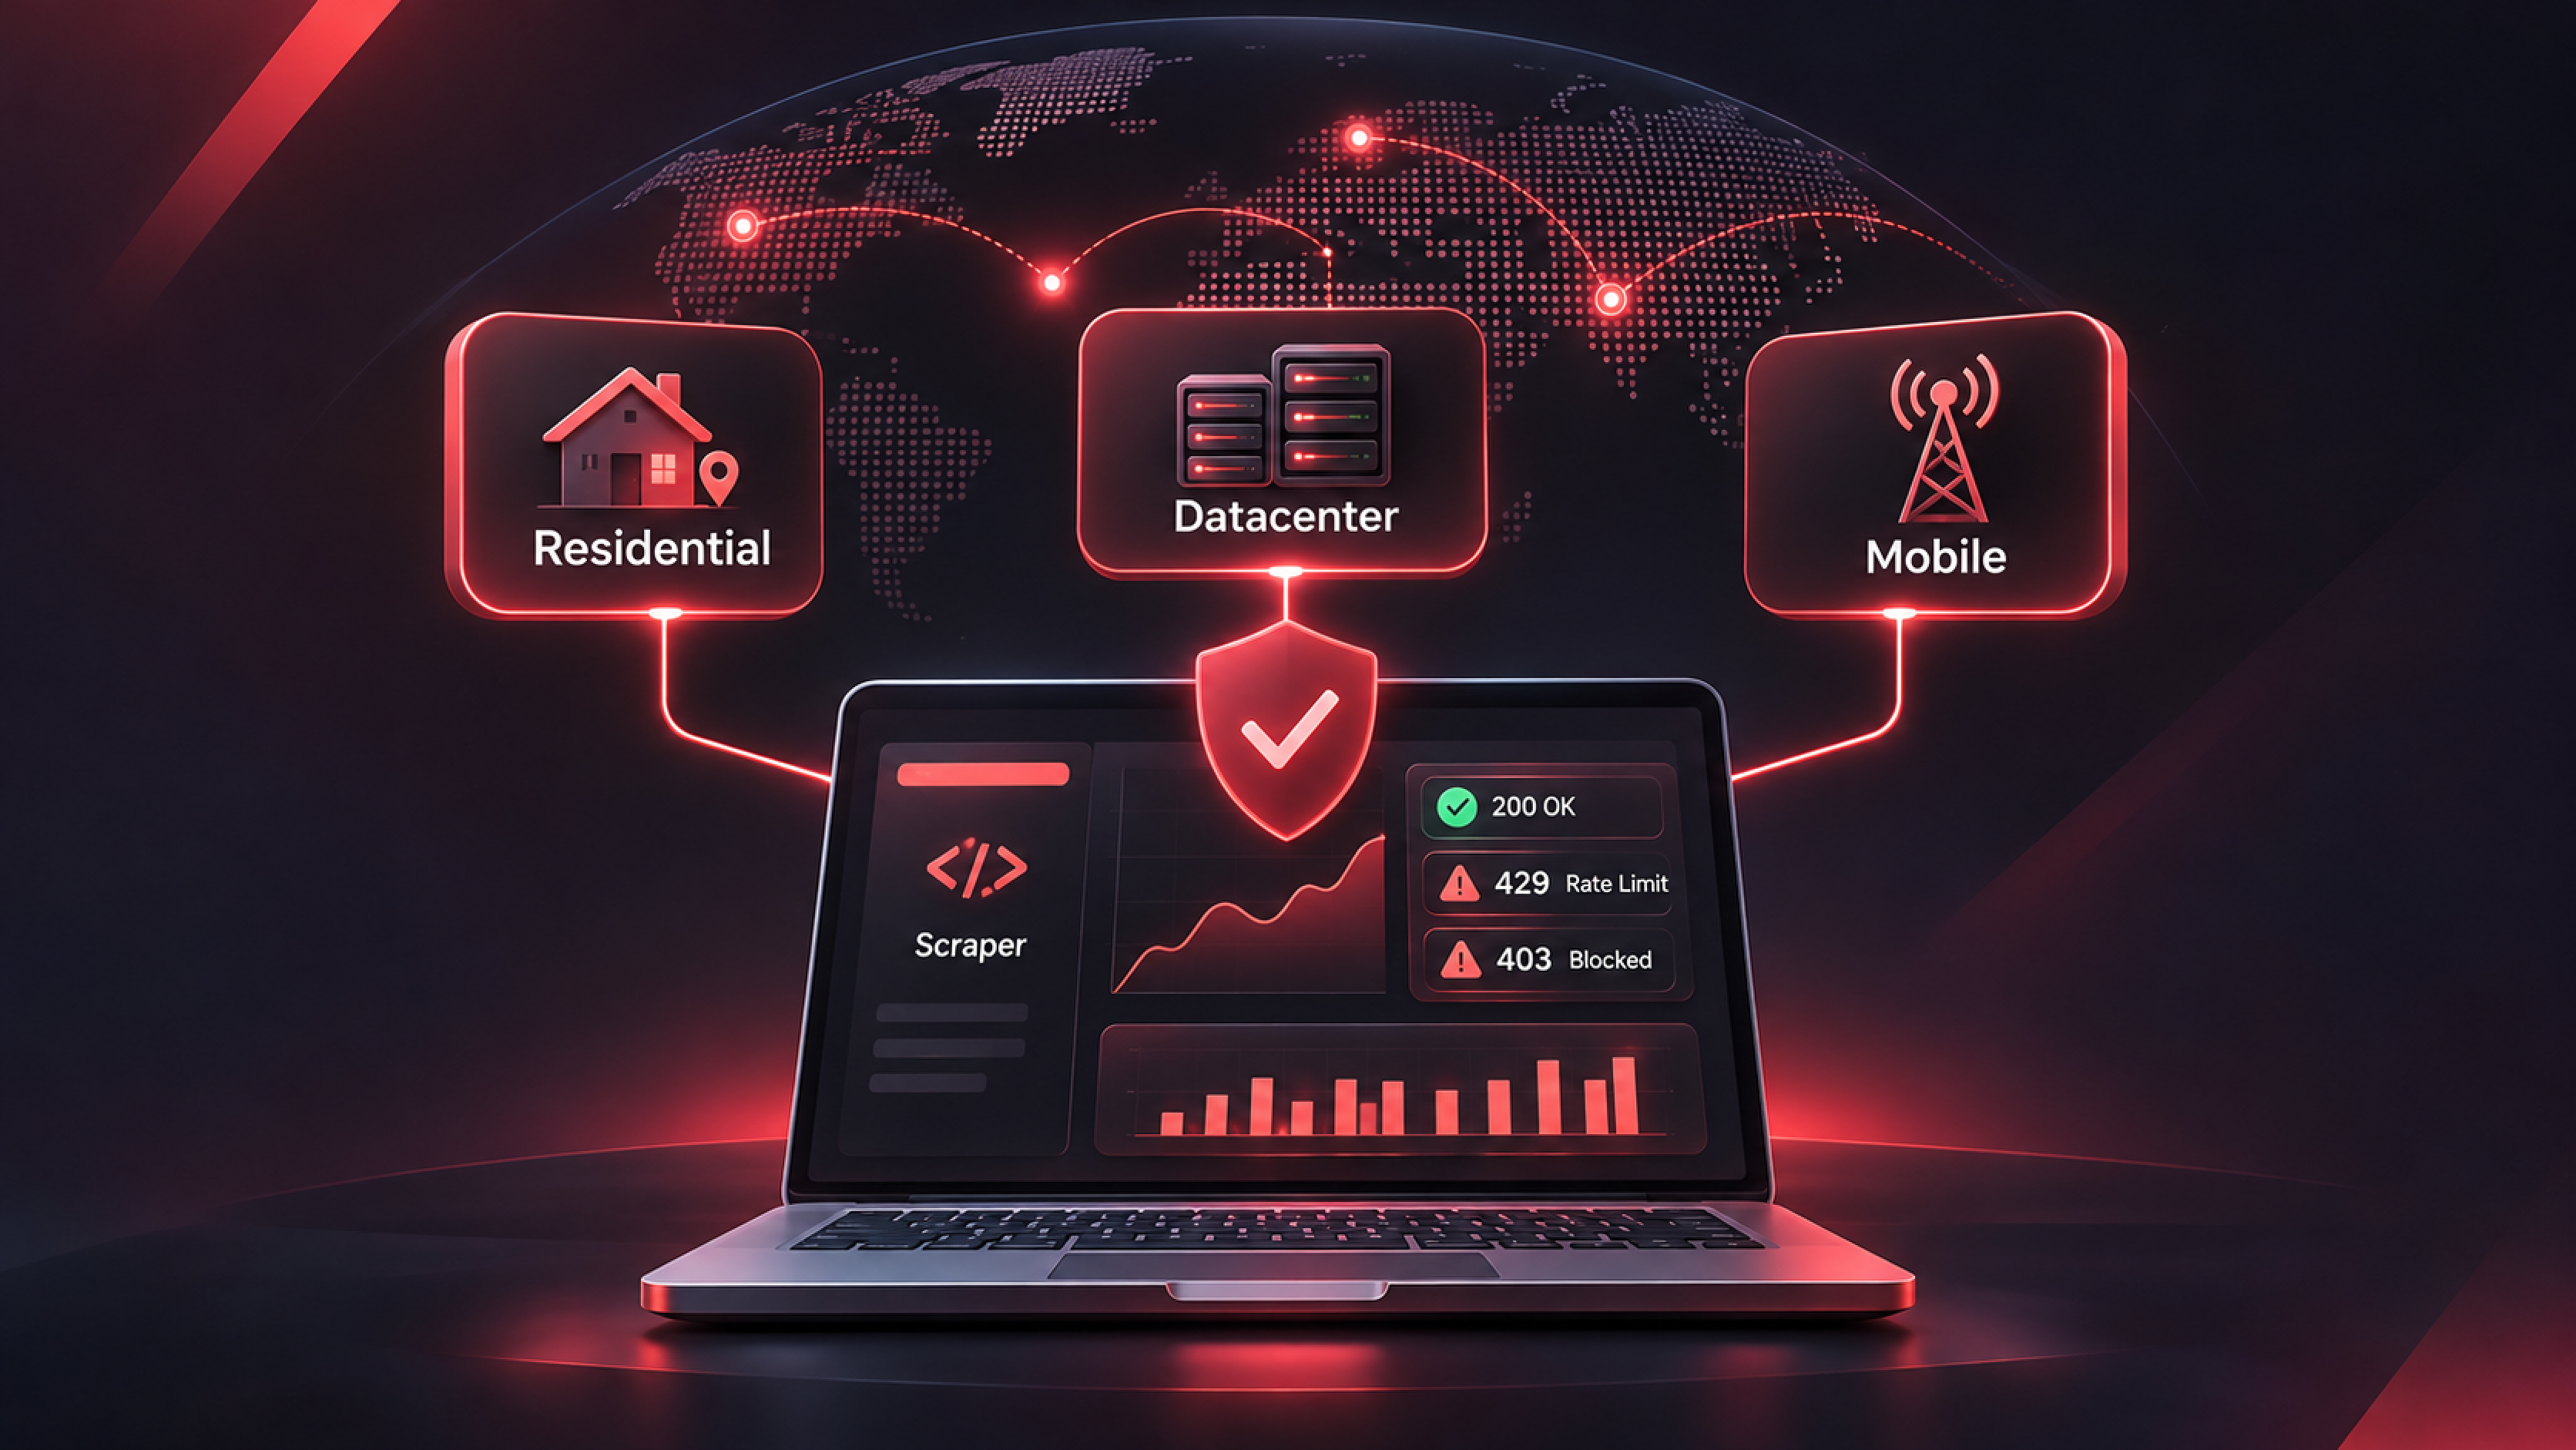
Proxy selection affects reputation, latency, geographic accuracy, and cost. The best option is not automatically the network with the largest advertised pool. Match the proxy category and rotation policy to the website's sensitivity and your session model.
Residential addresses are suitable for public pages that apply strict IP reputation or location checks. They generally resemble ordinary consumer connections and support country or regional targeting. Review IpnProxy residential proxy pricing when success rate and geographic coverage matter more than the lowest cost per request.
Datacenter proxies usually offer lower latency and predictable throughput. They work well for tolerant targets, search monitoring, testing, and high-volume public endpoints. Compare premium datacenter proxies when speed and concurrency are priorities.
Mobile IPs can be useful when a target serves mobile-specific content or relies heavily on carrier network reputation. They are typically more expensive, so reserve them for workloads where mobile origin is relevant. IpnProxy lists available options on its mobile proxy plans page.
Use an exit location that matches the requested market, language, currency, and availability rules. Avoid changing countries halfway through a session. Check the available proxy locations before designing regional jobs, and verify an active exit address with the IP lookup tool.
Rotating the IP for every request can damage consistency. If a site creates a session cookie on the first page, the next request should normally retain the same proxy, cookie jar, user agent, language, and relevant headers. This is commonly called a sticky session.
Assign one session identifier to one logical user journey. Keep the identity stable while browsing a category, moving through pagination, or completing a permitted search flow. Rotate only at a safe boundary, such as after the job finishes, the session expires, or the exit IP repeatedly fails health checks.
Do not invent dozens of browser headers without understanding them. Contradictory headers can be more suspicious than a small, internally consistent set. For JavaScript-rendered pages, use a real browser only when necessary because browser automation consumes substantially more CPU and bandwidth than direct HTTP requests.
Concurrency is the number of tasks running at once. Rate is the number of requests sent over time. Ten workers waiting between requests can be gentler than two workers making continuous calls. Control both values independently.
Begin with low concurrency and increase it in small steps. Record success rate, median latency, 95th percentile latency, 403 rate, 429 rate, bytes transferred, and cost per successful page. Stop increasing concurrency when latency or block rates rise faster than useful throughput.
Test every proxy route for connection success, external IP, country, DNS behavior, latency, and target-specific success. A proxy that reaches a generic test endpoint may still fail on the actual website. Run a small canary job before sending the full queue.
If your software prefers IPv6, confirm that the target and network path support it. The IpnProxy IPv6 compatibility checker can help identify connectivity mismatches. For connection formats, authentication details, and integration instructions, consult the IpnProxy documentation.
Confirm that cookies persist and that the same proxy remains attached to the session. Check whether pagination uses a token, cursor, or JavaScript request generated by the first page. Do not assume that changing the page number in the URL is sufficient.
Inspect request counts per IP and session. The target may use a rolling rate window. Reduce concurrency, lengthen delays, and introduce session cooldowns. Also check whether sticky sessions are expiring earlier than your job expects.
Save a redacted response sample and compare it with a valid page. Look for consent screens, localization redirects, bot challenges, login pages, and changed selectors. Treat content validation as part of request success rather than trusting the HTTP code alone.
Check proxy protocol, hostname, port, username encoding, password encoding, DNS resolution, certificate handling, and environment variables. Ensure the HTTP client sends HTTPS traffic through the correct tunneling method. Then reproduce the issue with one URL and one proxy before testing the complete crawler.
A durable scraper behaves like a controlled data pipeline. It sends requests at a measured pace, maintains coherent sessions, chooses proxies according to the target, and slows down when conditions change. That approach usually produces more valid pages with less traffic than aggressive rotation and unlimited retries.
IpnProxy provides residential, mobile, and premium datacenter options for different workload profiles. Review the supported proxy use cases, select a network that fits the target, and test it with a small representative sample before scaling production traffic.
Table of Contents
Summarize this article
Choose an AI assistant for a concise brief and practical takeaways.
Ready to get
started ?
Tags:


